📎

Matrix-Vector multiplication

Theory

w⃗=M⋅v⃗\small \vec w= M \cdot \vec v

(w1w2)undefinedw⃗=(abcd)undefinedM⋅(ef)undefinedv⃗ \underbrace{ \begin{pmatrix} w_1 \\ w_2 \end{pmatrix} }_{\vec w} = \underbrace{\small \begin{pmatrix} a & b \\ c & d \end{pmatrix} }_{M} \cdot \underbrace{ \begin{pmatrix} e \\ f \end{pmatrix} }_{\vec v} 

There are 2 ways to calculate this:https://www.youtube.com/watch?v=ebdfJwHM5vo

Method 1)

w[i]=∑0≤j<nM[i][j]⋅V[i]\small w[i] = \sum_{0 \leq j< n} M[i][j] \cdot V[i]

(abcd)⋅(ef)=((ab)⋅(ef)(cd)⋅(ef)) \small \begin{pmatrix} a & b \\ c & d \end{pmatrix} \cdot \begin{pmatrix} e \\ f \end{pmatrix} = \begin{pmatrix} \begin{pmatrix} a & b\end{pmatrix} \cdot \begin{pmatrix} e \\ f\end{pmatrix} \\ \\ \begin{pmatrix} c & d\end{pmatrix} \cdot \begin{pmatrix} e \\ f\end{pmatrix} \end{pmatrix} 

Method 2)

w⃗[j]=∑c0≤i<c1M[j][i]⋅v⃗[i]+∑c1≤i<c2M[j][i]⋅v⃗’[i]+⋯+∑cp−10≤i<cpM[j][i]⋅v⃗[i] \small \vec w[j] = \\ \quad ∑_{c_0≤i<c_1} M[j][i] \cdot \vec v[i] + \\ \quad ∑_{c_1≤i<c_2}M[j][i]\cdot \vec v’[i] + \\ \quad \dots + \\ \quad ∑_{c_{p-1}0≤i<c_p}M[j][i]\cdot\vec v[i] 

(abcd)⋅(ef)=e⋅(ac)+f⋅(bd) \small \begin{pmatrix} a & b \\ c & d \end{pmatrix} \cdot \begin{pmatrix} e \\ f \end{pmatrix} = e \cdot \begin{pmatrix} a \\ c \end{pmatrix} + f \cdot \begin{pmatrix} b \\ d \end{pmatrix} 

  • and the same also applies to matrices but slightly adapted

    (abcdef)⋅(ghijkl)=(gh)⋅(ad)+(ij)⋅(be)+(kl)⋅(cf) \small \begin{pmatrix} a & b & c\\ d & e & f \end{pmatrix} \cdot \begin{pmatrix} g & h\\ i & j \\ k & l \end{pmatrix} = \begin{pmatrix} g & h\end{pmatrix} \cdot \begin{pmatrix} a \\ d\end{pmatrix} + \begin{pmatrix} i & j\end{pmatrix} \cdot \begin{pmatrix} b \\ e\end{pmatrix} + \begin{pmatrix} k & l\end{pmatrix} \cdot \begin{pmatrix} c \\ f\end{pmatrix} 

The sequential algorithm is always in in O(n2)\small O(n^2) .

We now want to use collective operations to parallelize this.

Solution 1: Allscatter

Based on method 1

Tpar(p,n)=O(n2/p+n)\small \text{Tpar}(p,n) = O(n^2 /p+n) for n>log⁡p\small n > \log p

where:

O(n2/p)\small O(n^2/p) for local multiplication

O(n+log⁡p)\small O(n + \log p) for Allgather

Linear speedup for p≤n\small p \leq n .

Parallel algorithm

  1. Distribute n/p\small n/p rows of M\small M and v\small v to processors

    Now process k∈[0;p−1]\small k \in [0;~p-1] has some rows of M\small M and parts of v\small v .

    k⋅(n/p)≤j′<(k+1)⋅(n/p)\small k\cdot (n/p)≤j'<(k+1)\cdot (n/p)

    where j′\small j' is a subset of all rows j∈[0;n−1]\small j\in [0;~n-1] .

    Therefore j:=j′+k⋅(n/p)\small j := j'+k\cdot (n/p) .

  1. Use Allgather to get back v\small v from pieces v′\small v' on each process.

    Now process has some rows of M\small M and enitre v\small v .

  1. Calculate M′⋅v\small M' \cdot v locally

    w’[j]=∑0≤i<nM’[j][i]⋅v[i]\small w’[j] = \sum_{0≤i<n}M’[j][i]\cdot v[i]

    where j\small j is different for each process (and they iterate through i\small i locally).

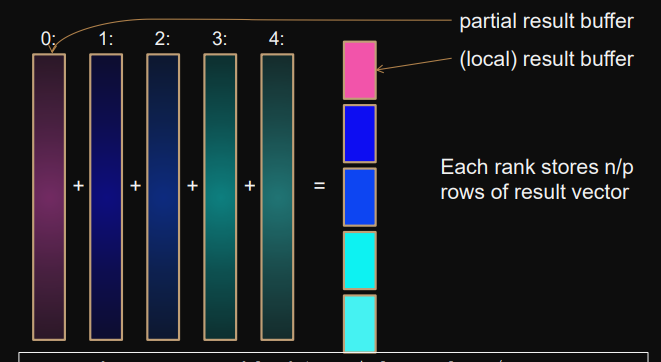
Solution 2: Reduce_scatter

Based on method 2

Tpar(p,n)=O(n2/p+n)\small \text{Tpar}(p,n) = O(n^2 /p+n) for n>log⁡p\small n > \log p

where:

O(n2/p)\small O(n^2/p) for local multiplication

O(n+log⁡p)\small O(n + \log p) for Reduce_scatter

Linear speedup for p≤n\small p \leq n .

Parallel algorithm

  1. Distribute M\small M column-wise, and \smallv\small v row-wise.

    Processor k∈[0;p−1]\small k \in [0;~p-1] has columns j∈[ci;ci+1]\small j \in [c_i;~c_{i+1}] of M\small M . \small

    where ci=k⋅(n/p)\small c_i = k\cdot(n/p)

    and n/p\small n/p rows of v\small v .

  1. Calculate M′⋅v′\small M' \cdot v' locally

    ∑cx≤i<cx+1M’[j][i]⋅v⃗’[i] \small ∑_{c_{x}≤i<c_{x+1}}M’[j][i]\cdot\vec v’[i] 

  1. Calculate sum of the result vectors of each process

    w⃗′[j]=∑c0≤i<c1M’[j][i]⋅v⃗’[i]+∑c1≤i<c2M’[j][i]⋅v⃗’[i]+⋯+∑cp−10≤i<cpM’[j][i]⋅v⃗’[i] \small \vec w'[j] = \\ \quad ∑_{c_0≤i<c_1}M’[j][i] \cdot \vec v’[i] + \\ \quad ∑_{c_1≤i<c_2}M’[j][i]\cdot \vec v’[i] + \\ \quad \dots + \\ \quad ∑_{c_{p-1}0≤i<c_p}M’[j][i]\cdot\vec v’[i] 

MPI_Reduce_scatter_block(partial,result,n/p,MPI_FLOAT,MPI_SUM,comm);
for (i=0; i<p; i++) counts[i] = n/p;
MPI_Reduce_scatter(partial,result,counts,MPI_FLOAT,MPI_SUM,comm);